Babel Street vs. Identity Matching Alternatives
Determining whether records represent the same person or organization is complicated by language differences, transliterations, aliases, typos, and incomplete data. Basic matching can miss genuine connections or mistake similar records for the same identity, making confident identity decisions difficult.
Babel Street Match combines multilingual and multi-attribute matching with regional name intelligence, semantic matching, configurable scoring, and identity record resolution to help organizations make faster, more accurate, and more explainable identity decisions.
How is Babel Street different from traditional identity matching tools?
Traditional identity matching tools often rely on exact matches, string similarity, phonetic matching, and basic fuzzy matching to identify potential connections between records. Babel Street Match goes beyond these approaches by combining multilingual and cross-script matching, regional naming intelligence, semantic analysis, and configurable scoring. This helps organizations identify relationships across different languages, account for aliases and spelling variations, reduce false positives, and resolve fragmented identity records while maintaining control over matching decisions.
The challenge with identity matching alternatives
Many identity matching solutions rely heavily on exact matches, string similarity, phonetic similarity, fixed rules, or relatively simple fuzzy matching. Those approaches can struggle when organizations need to:
- Match identities across different languages and writing systems
- Account for transliterations, aliases, spelling variations, and cultural naming conventions
- Determine whether similar names represent the same person
- Incorporate addresses, dates, identifiers, and other identity attributes
- Resolve fragmented and duplicate identity records across systems
- Balance false positives against the risk of missed matches
- Explain why a particular record received its matching score
- Adapt matching logic to different populations, missions, and risk tolerances
Exact matching can miss real identities because even minor differences, such as typos, formatting variations, shortened names, missing accents, or transliterations, can prevent a match. The challenge is determining whether different records are likely to represent the same real-world identity with enough confidence to act.
Identity matching alternatives vs. Babel Street
| What Organizations Need | Basic Identity Matching Alternatives | Babel Street |
|---|---|---|
| Exact name matching | ✅ | ✅ |
| Fuzzy matching | ✅ | ✅ |
| Multilingual and cross-script matching | ❌ Varies | ✅ 20+ languages and scripts |
| Transliteration and variant handling | ❌ Varies | ✅ |
| Regional naming intelligence | ❌ Limited | ✅ |
| Multi-field identity matching | ❌ Varies | ✅ |
| Semantic organization-name matching | ❌ Limited | ✅ |
| Configurable field scoring | ❌ Limited | ✅ |
| Identity record resolution | ❌ Varies | ✅ |
| Explainable matching decisions | ❌ Varies | ✅ |
Four reasons organizations move beyond basic identity matching
The language problem
Identity data does not conform to a single language, alphabet, or naming convention. A person or organization name can appear differently across languages and scripts, and transliteration can produce multiple valid versions of the same name. Exact and basic fuzzy matching can therefore miss legitimate connections or generate unnecessary candidates.
Babel Street Match works across more than 20 languages and scripts and accounts for transliteration, spelling variation, and cultural naming nuances. Cross-lingual semantic matching can also evaluate meaning and linguistic structure where two names may share little obvious string or phonetic similarity.
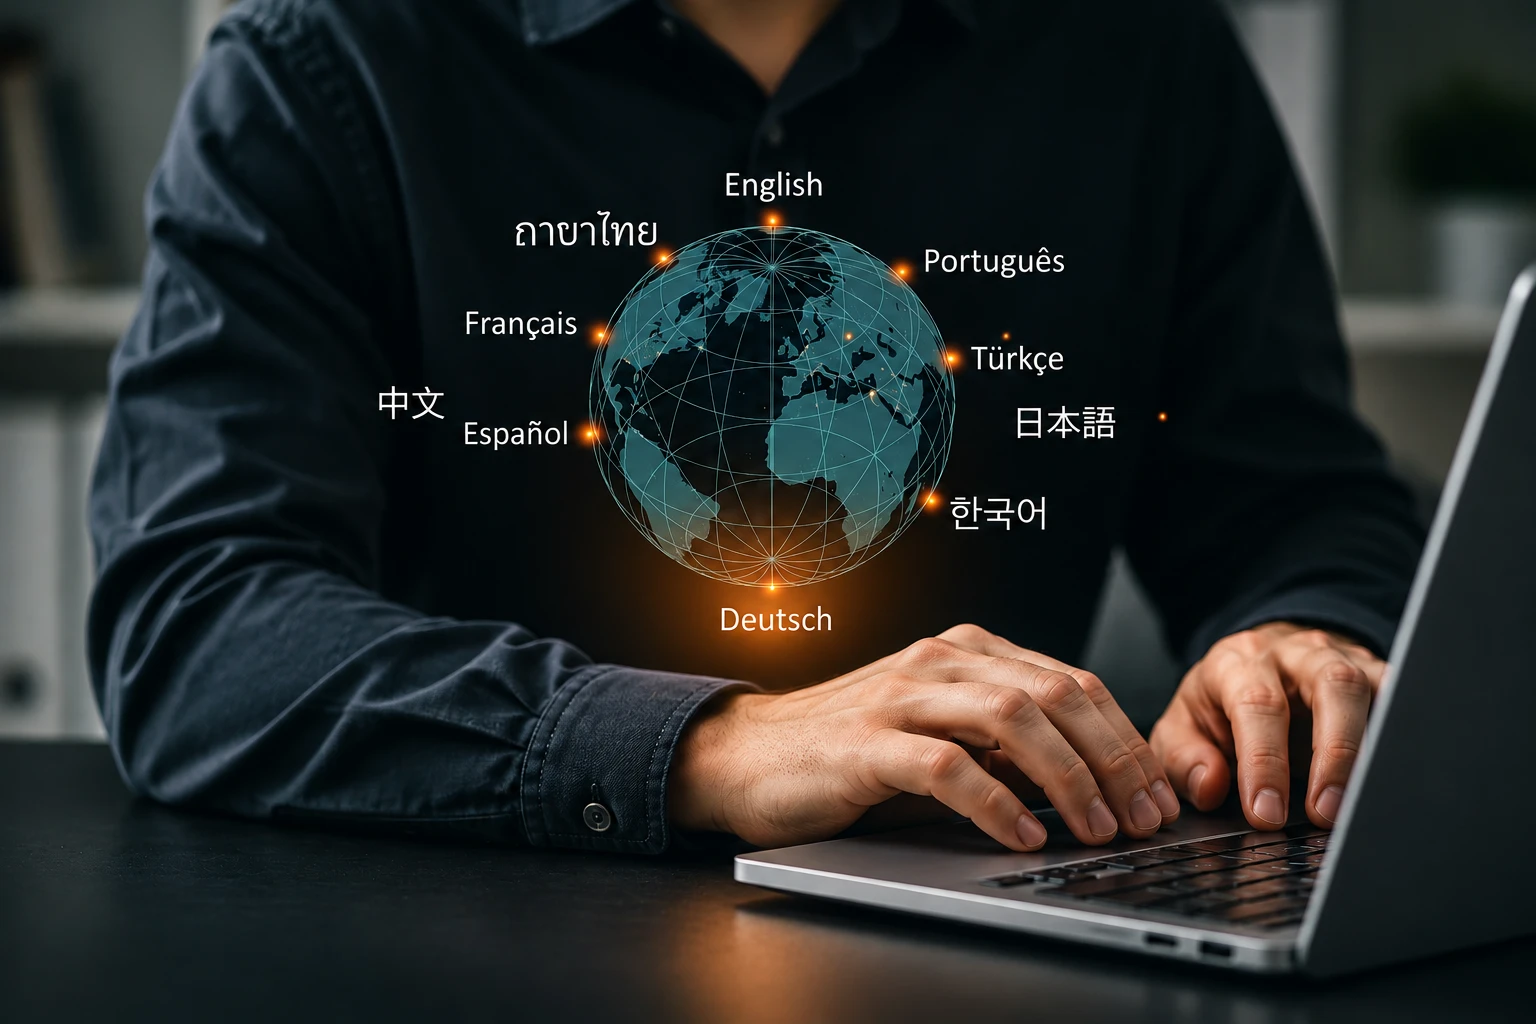
Beyond name matching
Identity is bigger than a name.
Babel Street helps organizations:
- Compare identity information across more than 20 languages and scripts
- Account for aliases, transliterations, spelling variations, and incomplete data
- Evaluate names alongside addresses, dates, and other identifiers
- Apply regional naming context to identity scoring
- Connect semantically equivalent names across languages
- Configure how different identity fields influence match confidence
- Identify and resolve fragmented or duplicate identity records
- Reduce unnecessary review while maintaining sensitivity to meaningful matches
That broader approach turns matching from a simple record-comparison exercise into a foundation for trusted identity decisions.
Human judgment remains essential
Identity matching requires more than maximizing a mathematical similarity score.
Different organizations have different consequences for getting a match wrong. A financial institution performing sanctions screening, a border agency evaluating a traveler, and an organization attempting to clean duplicate records may apply different thresholds depending on their risk profile.
With over one hundred tuning parameters, Babel Street allows organizations to configure and govern identity matching according to their requirements while preserving traceability.
The result is greater confidence in the identities behind the data.
Ready to learn more? Speak with an expert
Frequently asked questions
What is identity matching?
Identity matching compares data such as names, aliases, addresses, dates, and identifiers to determine whether different records likely refer to the same real-world person, organization, or entity.
What makes Babel Street different from basic fuzzy matching?
Basic fuzzy matching primarily identifies strings that are similar but not identical. Babel Street combines fuzzy matching with multilingual and cross-script expertise, transliteration, regional naming intelligence, semantic analysis, multi-field matching, and configurable scoring to make identity decisions using broader context.
How does Babel Street reduce false positives?
Babel Street evaluates multiple identity attributes and matching signals rather than relying solely on name similarity. Regional naming intelligence adds likely regional context, while configurable field scoring allows organizations to control how names, dates, addresses, identifiers, and other fields affect overall match confidence.
What is the difference between identity matching and identity resolution?
Identity matching determines whether records are likely to represent the same person or organization. Identity resolution goes further by grouping and resolving records that likely represent the same real-world identity, creating cleaner and more reliable identity data for subsequent workflows.
Can Babel Street match identities across different languages and scripts?
Yes. Babel Street Match supports more than 20 languages and scripts and handles transliteration, spelling variations, cultural naming conventions, and cross-lingual matching.
Where can organizations use Babel Street identity matching?
Babel Street Match supports identity-intensive workflows including sanctions screening, AML/KYC, border security, fraud investigations, identity verification, government and law-enforcement databases, and broader risk intelligence applications.
Can organizations configure Babel Street Match for their own risk tolerance?
Yes. Configurable field scoring lets organizations determine how individual identity fields influence overall match confidence, providing greater control over matching decisions and allowing the technology to align with customer-specific risk models.